Scoring engines
Three engines vote on every report. Each one looks at the body through a different lens, returns a 0–100 score, and is combined as a weighted sum. This page is the landing point for the Score Fusion stage of the pipeline — a single index of every engine, what it sees, what it can't see, and where it's known to misfire.
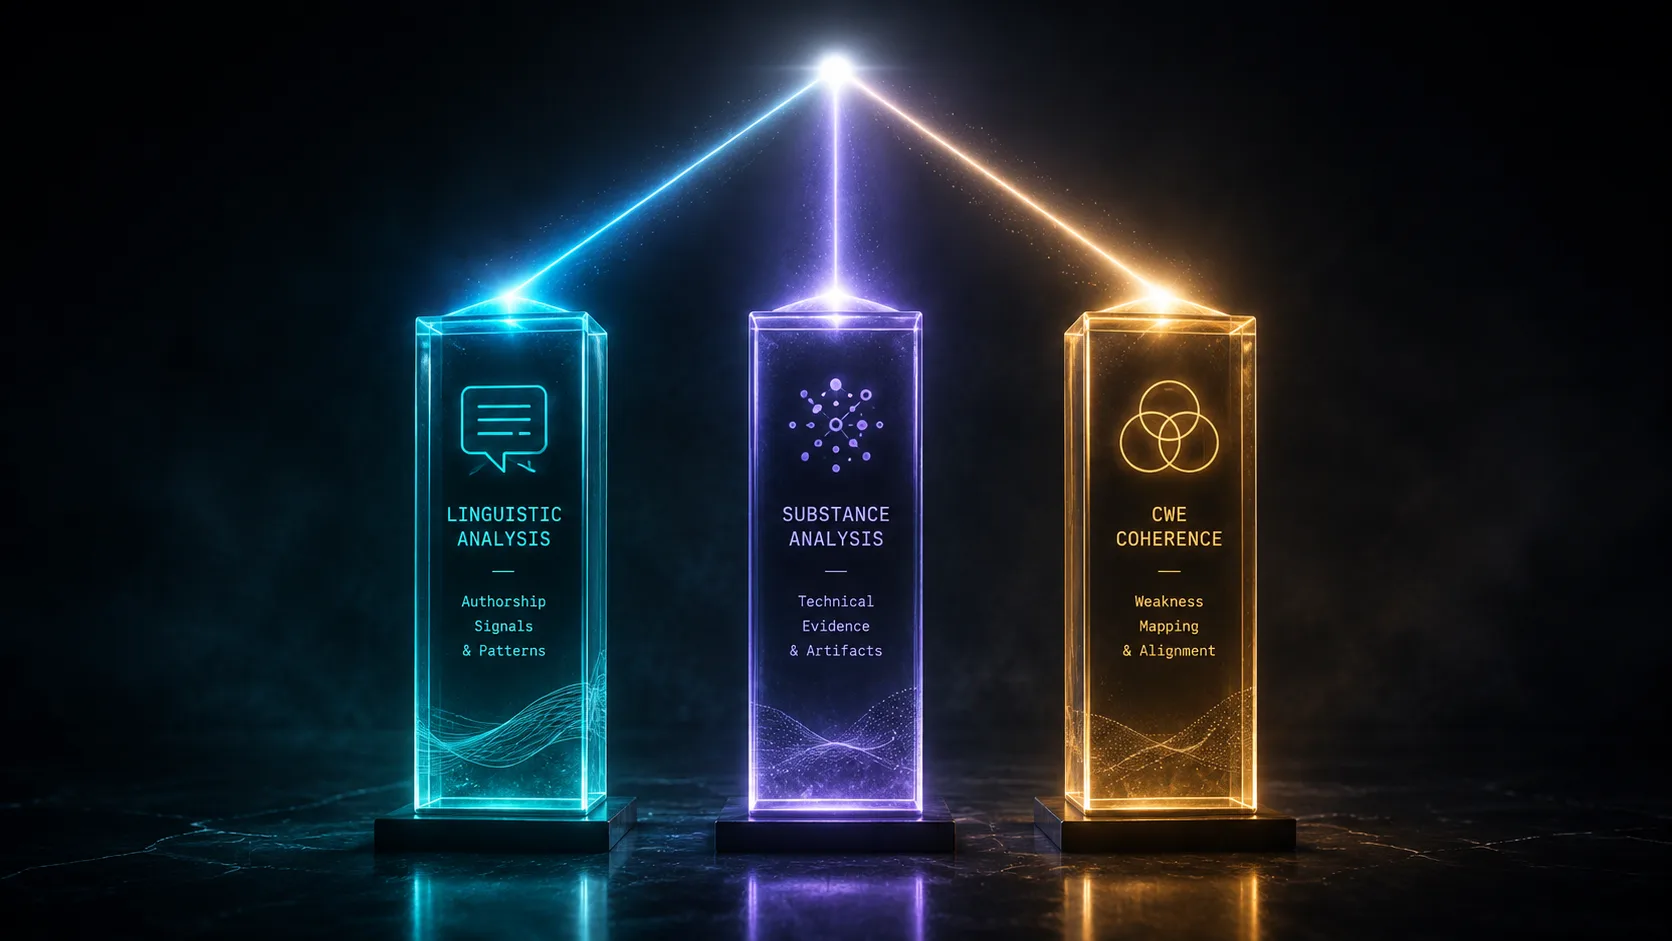
E1 (AI Authorship) is inverted — a high score means the prose looks machine-generated, which lowers the composite. E2 (Substance) carries the most weight because its signals are nearly impossible to fabricate. E3 (CWE Coherence) is gated by E2 so that naming the right CWE in an evidence-free report can't lift the composite into borderline territory.
Detects machine-generated prose patterns — burstiness, vocabulary, repetitive scaffolding.
- Sentence-length burstiness vs. expert baseline
- Vocabulary richness and rare-word density
- Stock LLM scaffolding phrases ('It is important to note that…')
- Inverted in the composite: high score → likely AI-written → penalised
- A human reporter who writes blandly will look LLM-ish
- An LLM polishing genuine technical content can score low
- Non-native English writing is intentionally not penalised
- Generated security templates from internal tooling
- Reports translated through a model from another language
- Highly repetitive but legitimate disclosures (mass-assignment lists)
Counts concrete, verifiable artifacts — code blocks, file paths, line numbers, real URLs, repro steps.
- codeEvidence (35%) — language-tagged fenced code that's actually copy-pasteable
- references (30%) — file paths, line numbers, endpoints, version numbers
- reproducibility (20%) — explicit steps, environment, real working URLs
- pocIntegrity (10%) — does the claimed PoC actually exist in the body?
- claimEvidence (5%) — ratio of asserted claims to evidence backing them
- A bug whose evidence is binary or visual (a video repro, a memory dump)
- Theoretical / design-flaw reports where there is no line number to point at
- Any vulnerability that can only be described prose-first (cryptographic protocol flaws)
- Hardware bugs and side-channel research often lack file paths
- Race conditions where the only evidence is a timing trace
- Reports that link to a private repo the engine cannot read
Checks whether the body actually describes the CWE the title claims.
- Term-frequency classifier across the full CWE catalogue
- Soft citation: which CWE the body actually sounds like
- Parent ↔ child relationships count as soft matches, not mismatches
- Gated by Engine 2 — naming the right CWE is cheap when there is no evidence
- Chained bugs that legitimately cross CWE boundaries (SSRF → RCE)
- Vendor-specific taxonomies that don't map cleanly to CWE language
- Reports too short for the classifier to commit to any CWE — abstains rather than guesses
- A genuine cross-CWE chain where the title picks one link and the body emphasises another
- Family vs. specific drift (CWE-79 cited, CWE-80 described)
- In-house bug taxonomies translated into CWE numbers post-hoc
Family-aware rubric layer that sits behind Engines 2 and 3. Picks a weakness family first, then judges the report against the rubric for that family rather than one flat checklist.